What is a YouTube scraper?
A YouTube scraper is a tool or workflow that collects selected information from YouTube pages into a structured result, such as a CSV of video titles, view counts, and publish dates. With ego(lite), the scraper is your own AI agent working in a visible browser: it opens each public video, channel, or playlist page in a separate Space and records the fields the page displays, together with the source URL, checked-at time, and access status.
How does YouTube scraping work with ego(lite)?
Give Codex or Claude Code the prompt on this page plus your video, channel, or playlist URLs and the fields you need. The agent opens each source in a separate ego(lite) Space, copies the values the page visibly displays, and returns CSV or Markdown rows with a status for every source. If YouTube asks for sign-in, consent, or another human decision, it stops in that Space and lets you review or take over.
Can I use it as a YouTube channel scraper?
Yes. Point the agent at a public channel videos page and it records the channel fields the page displays, including the subscriber count, video count, and About text. It also captures the visible video list with titles, URLs, and displayed view counts. Values are copied exactly as YouTube shows them (including rounded counts like “1.2M”), and anything the page does not display stays marked as not displayed.
Can it scrape a YouTube playlist?
Yes. Used as a YouTube playlist scraper, the agent opens the playlist page, lists the videos it can see, and then records the requested fields one video at a time in separate Spaces. Long playlists take proportionally long because each video is a real page visit, and the run summary shows the status of every entry instead of silently skipping failures.
Is this a YouTube scraper API?
No. ego(lite) is an agent-driven browser workflow, not a hosted API endpoint. There are no API keys, credits, or JSON quotas. If you need thousands of rows per day inside a server-side pipeline, the official YouTube Data API or a dedicated service is the better fit. This workflow is for bounded lists where you want the run observable and every row source-linked.
Is scraping YouTube allowed?
YouTube's Terms of Service restrict automated access, and rules differ by jurisdiction and use, so review them before you run any collection. This workflow is deliberately conservative: it reads only public values your own browser session already displays, respects sign-in walls, region blocks, CAPTCHAs, and rate limits instead of bypassing them, and keeps a source trail for review. None of this page is legal advice.
Can it scrape YouTube comments?
Only the comments the page visibly loads in your session, for a small, bounded list of videos. The agent can record visible comment text with its video source, but it will not paginate through thousands of comments or reconstruct threads the page never displayed. For large comment datasets, the official YouTube Data API is the appropriate tool.
Can it download YouTube videos?
No. The output is text and metadata: titles, URLs, displayed counts, dates, statuses, and check times. The workflow does not download video or audio files, and it is not a tool for saving copies of media.
Can it extract video transcripts or subtitles?
Yes, through the dedicated transcript workflow. The agent opens YouTube's own “Show transcript” panel and saves what it displays, with the caption language and auto-generated label preserved. See the YouTube transcript extractor page for the full prompt and its boundaries. Videos without captions stay marked instead of being transcribed from audio.
Is ego(lite) a free YouTube scraper?
ego(lite) is free to download for Mac, and the agent doing the work is your own Codex or Claude Code. There are no scraping credits, per-row charges, or sign-up walls in this workflow. What it can record is limited by what your browser session can see, not by a meter.
How is this different from scraper APIs and no-code crawlers?
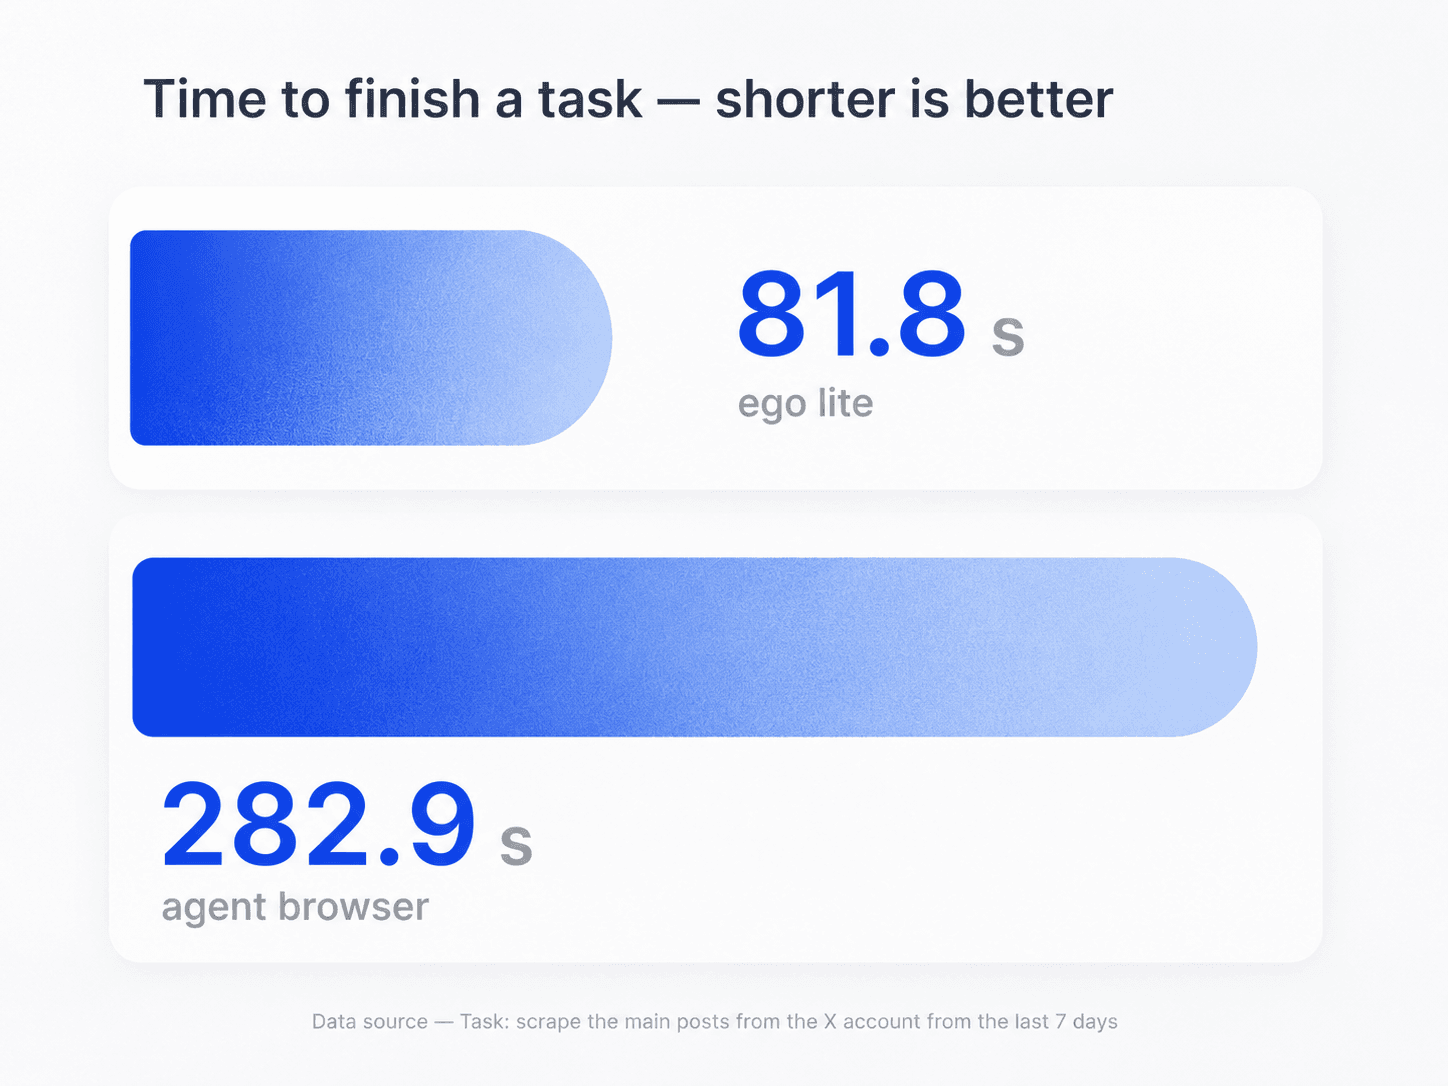
Scraper APIs and no-code crawlers run in someone else's cloud, meter output by credits, and often sell proxy rotation and bot-detection handling. ego(lite) runs in a visible browser on your Mac with the agent you already use: the scope stays bounded by your input list, nothing is bypassed, and every row keeps its source URL, checked-at time, and access status so results stay reviewable.
What happens when YouTube shows a CAPTCHA or rate limit?
The agent stops in that Space and records the visible restriction instead of solving or bypassing it. You can inspect the browser state, complete an authorized step yourself if appropriate, or end the run. The report keeps the source, time, and blocked status so a limited result is never mistaken for a complete one.
How do I export YouTube comments to CSV?
Give the agent a small list of public video URLs and ask it to record only comments currently loaded in each page, together with the video URL, author label as displayed, text, and checked-at time. It can return CSV or Markdown, but it will not pretend that a page with collapsed or unavailable comments is a complete dataset. For large comment volumes, use the official YouTube Data API and review its quota and terms.
Can I use this to summarize a channel or prepare an AI content workflow?
Yes, as a two-stage workflow: first collect a bounded, source-linked list of videos, titles, dates, and visible descriptions or transcripts; then ask your chosen model to summarize those rows and cite the original URLs. Keep collection and interpretation separate so an inferred theme is not mistaken for a value YouTube displayed, and review any draft before publishing or replying to viewers.
Can I scrape YouTube without an API key?
For a small, manual or agent-reviewed list of public pages, the browser workflow does not require a YouTube API key. It reads what your current session visibly displays and records access limits. That is not a replacement for an API at scale: do not turn a no-key browser run into an unbounded crawler, and use the official API when you need scheduled server-side collection or quota accounting.
How do I clean YouTube transcripts for RAG?
Capture the transcript panel exactly as displayed, preserve the video URL, title, language, and whether captions are auto-generated, then remove navigation noise and split the text into timestamped chunks before indexing. Keep a source URL and retrieval time on every chunk, and mark videos with no transcript instead of generating one from audio without permission.
How do I compare YouTube scrapers such as Apify and an API?
Compare the same source list and fields on completeness, freshness, source traceability, access handling, latency, and total cost. A hosted scraper may offer scale and managed infrastructure; ego(lite) offers a visible, bounded browser run with your agent and no per-row credits. Neither comparison nor a demo proves that a tool is allowed to bypass YouTube restrictions or that it can recover unavailable data.
Can an AI agent manage a YouTube channel or reply to comments automatically?
It can prepare a source-linked report, draft a summary, or stage a reply for your review when the page and account permit it. This scraper workflow does not publish, like, subscribe, or mass-reply, and it stops at sign-in, consent, CAPTCHA, or rate limits. Use the official YouTube APIs and explicit channel permissions for approved publishing workflows, with a human approval step.