The short answer: Browser Use owns an autonomous browser-agent loop; Stagehand gives developers a CDP-native SDK that mixes deterministic code with AI primitives; ego (lite) hands the agent a full Chromium to drive. Choose by who should own the next action, not by a feature checklist.
We installed the current Browser Use and Stagehand packages, ran the same read-only Hacker News extraction, and repeated it in an ego (lite) Space on August 25, 2026. The useful result was not a winner's podium. It was seeing exactly where autonomous extraction needed validation and where deterministic control rescued the task.
Disclosure: we build ego (lite).
What is the core difference?
The comparison becomes much easier when you separate autonomy from browser control. Browser Use is an agent framework. Stagehand is an SDK for browser agents. ego (lite) is a browser made available to an external coding agent.
| Decision factor | Browser Use | Stagehand | ego (lite) |
|---|---|---|---|
| Primary role | Autonomous agent loop and browser runtime | Hybrid SDK for deterministic and AI actions | Persistent real browser for shell-capable agents |
| Current runtime checked | Python 3.11+; package 0.13.8 | Node 22.18+ for the TS SDK; package 4.0.2 | Installed macOS app and CLI 0.4.7.1 |
| Who chooses the next action? | The configured model inside Browser Use's loop | Your code, with AI exactly where you call it | Your coding agent, through scripts and CDP |
| Official language surface | Python | TypeScript, Python, and Go | Any agent that can run its shell skill |
| Best default fit | Unknown routes that require exploration | Browser workflows maintained in a codebase | Coding-agent tasks in a persistent personal browser |
Browser Use: the model owns the route
Browser Use is an MIT-licensed Python framework with an Agent that observes the page, decides what to do, acts, and repeats. That is the right abstraction when the route cannot be written in advance. It also means model choice, prompts, timeouts, output validation, browser profiles, and infrastructure are part of your system.
Stagehand: code owns the route
Stagehand is Browserbase's open-source browser-agent SDK. Current Stagehand is CDP-native rather than built on Playwright, but it deliberately exposes familiar browser APIs. Version 4 adds a fourth high-level primitive, agent, beside act, extract, and observe. Its strongest pattern is deterministic navigation with a narrow AI call at the uncertain edge.
ego (lite): the browser your coding agent works in
ego (lite) does not add another planning model. A coding agent such as Codex or Claude Code writes a JavaScript workflow and runs it in the browser, a full Chromium where modern JavaScript apps, dynamically rendered pages, cross-origin iframes, and shadow DOM render and respond normally, with no patches or workarounds.
What happened in our matched test?
The task was deliberately small and falsifiable: open Hacker News and return the current first three ranked story titles with each visible integer point count. Success required the three values to match the source page. No login, vote, comment, message, or other mutation was allowed.
| Mode | Observed result | Success criterion |
|---|---|---|
| Browser Use Agent + local qwen3:4b | Three attempts; model step timed out before a structured result | Failed in this configuration |
| Browser Use BrowserSession + page evaluation | Returned the visible first three rows in 4.92 seconds | Passed |
| Stagehand AI extract + local callback | Filled the schema with ranks 22 to 24 instead of 1 to 3 | Failed despite valid shape |
| Stagehand local browser + page evaluation | Returned the visible first three rows in 13.35 seconds | Passed |
| ego-browser Space + page evaluation | Returned the visible first three rows in the first CLI round | Passed |
Browser Use: the browser worked, the local agent path did not
The first clean install completed, then Browser Use downloaded three default extensions on first launch. Its Agent opened the correct HN page, but the native local-model call timed out repeatedly. Attempt one hit four 75-second model timeouts. Attempts two and three used a 180-second model timeout and still did not leave step one with a structured result.
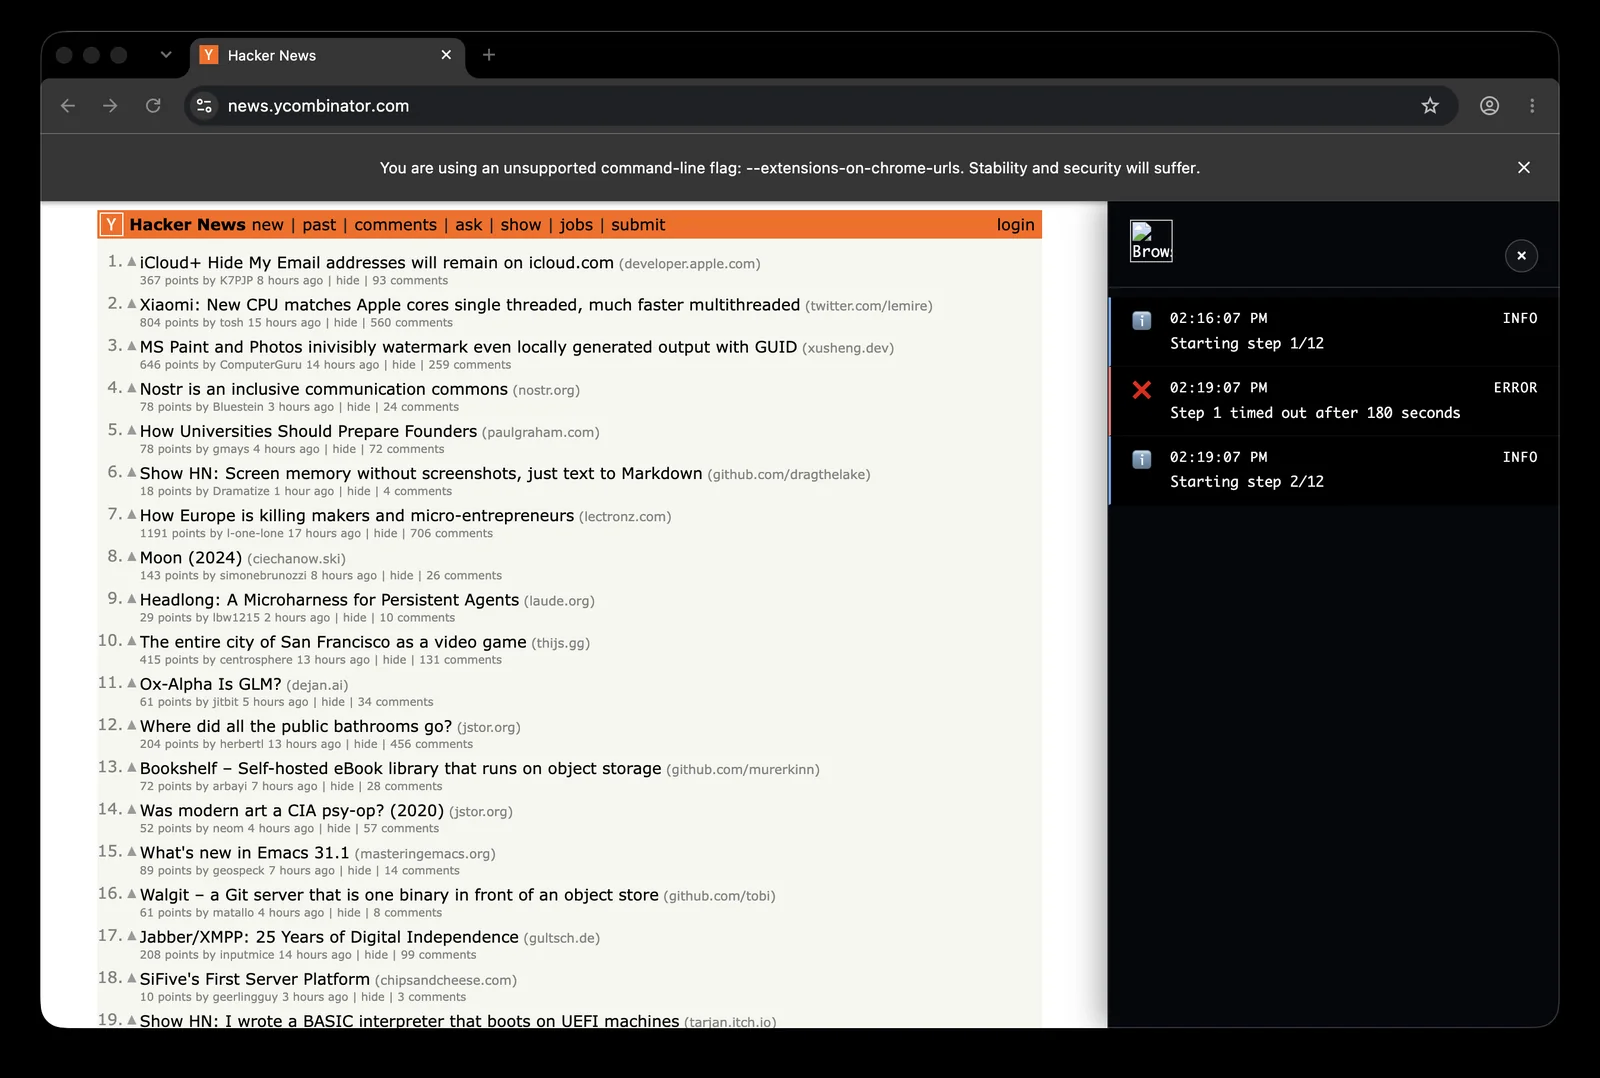
We then removed the model from the route and used Browser Use's own BrowserSession plus actor Page.evaluate. The same installed browser layer returned the correct visible rows in 4.92 seconds. That split matters: a failed model loop is not the same thing as a failed browser runtime.
Stagehand: a valid schema hid a wrong answer
Stagehand's AI extract was more dangerous than a hard error. It returned exactly three objects with a string title and integer points, but they belonged to rows near the bottom of the page. The source page showed different stories at ranks one through three. Stagehand's own log called the extraction incomplete after processing all data.
[stagehand] Extraction incomplete after processing all data
wall time: 109.90s
inference: 96.67s | prompt: 4,228 tokens | completion: 133 tokens

AI result started with:
1. Octopus intelligence may be related to never-before-seen mutation
2. Show HN: A Modern GUI Library for Ada...
3. Crafting QR Codes...

Visible page ranks 1-3 started with:
1. iCloud+ Hide My Email addresses will remain on icloud.com
2. Xiaomi: New CPU matches Apple cores...
3. MS Paint and Photos invisibly watermark...
A deterministic Stagehand page evaluation then returned the correct rows in 13.35 seconds. This is the strongest argument for Stagehand's hybrid design: use extract where semantic uncertainty is real, but keep selectors, invariants, and source-page checks around results that must be exact.
ego (lite): one deterministic round in an agent Space
The installed ego-browser CLI created a named Space, opened HN, and evaluated the same DOM rule in the first round. No second browser-agent model or provider key was added because the existing coding agent wrote the browser-side script. The app kept the task visible in its own Space with a live takeover surface.
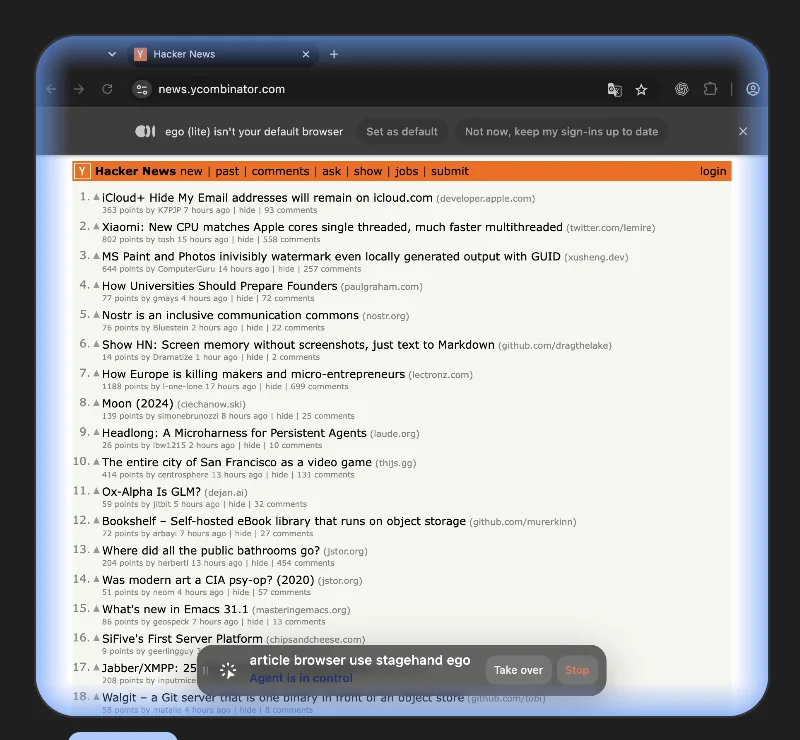
There was still friction. The installed ego-browser skill document named a captureScreenshot helper that runtime 0.4.7.1 did not expose. We used the same Space's CDP screenshot path instead, recorded the mismatch, and closed the Space after verification. A packaged workflow is not exempt from version drift.
Which browser agent is ready for production?
There is no production winner independent of the operating model. Browser Use is the clearest fit when an autonomous agent must discover a route. Stagehand is a better fit when a team owns a codebase and wants AI primitives beside deterministic browser code. AgentQL is a query-oriented option for teams that want natural-language data shapes over a Playwright browser, while Skyvern is a workflow platform to evaluate when a visual, service-managed process matters more than embedding a browser SDK. The browse CLI is a useful local comparison when the agent should call a small command surface.
Treat those labels as starting points, not guarantees. Before adopting any of them, run your own read-only acceptance task against the pages, account states, and output schema you actually need. Measure completion rate, recovery after a failed step, evidence captured, operator intervention, and cost per successful result. A tool that looks autonomous in a demo can still require a queue, retries, a validator, and a human escalation path in production.
| Production question | What to verify |
|---|---|
| Can it recover? | Retry limits, timeout state, and a resumable session rather than a blind replay |
| Can it be audited? | URL, inputs, extracted output, screenshots or logs, and the final validation decision |
| Can it be contained? | Separate profiles or Spaces, domain policy, scoped credentials, and a stop or takeover control |
What does one browser-agent execution cost?
The useful unit is cost per successful result, not the advertised token price. Add model input and output tokens, browser or session minutes, network or proxy charges, storage, retries, and the human time spent reviewing failures. A 100-token extraction that must be rerun three times can be more expensive than a longer deterministic script that succeeds once.
Stagehand's documented act, extract, and observe primitives let you keep model calls narrow; Browser Use may spend more model turns while it discovers a route; ego (lite) can avoid a second browser-planning model when your coding agent already writes the steps. Record these as separate line items rather than claiming that one product is universally cheapest. Our matched run was an engineering observation, not a cross-provider price benchmark.
How should agents handle login and CAPTCHA?
Handle authentication as a state transition, not as a challenge to defeat. Give the agent a least-privilege profile, navigate to the login page, and pause for the account owner to enter passwords, one-time codes, or passkeys. Resume only after the page exposes a verifiable signed-in state. Keep CAPTCHA, WAF, and rate-limit responses as explicit stop conditions; do not automate solving or evade a site's access controls.
For a deeper threat model, read our browser-agent security checklist. It covers prompt injection, credential boundaries, approval gates, and the kill switch that should exist before an agent can reach a valuable account.
How do you automate websites that change often?
Use a layered contract. Keep navigation and high-risk actions deterministic where possible, prefer accessible names and stable data attributes over coordinates, and reserve AI observation for the uncertain edge. After every extraction, assert the URL, record count, required fields, and a source-page checksum or visible label. When the contract fails, save the page evidence and stop for repair instead of letting the agent guess.
Self-healing selectors can reduce maintenance, but they do not prove that the meaning of a field stayed the same. Run a small canary task after a site release, pin package versions, and keep a fallback path. The right response to a frequently changing website is observable recovery, not an unbounded retry loop.
How do you prevent an AI extraction from returning wrong numbers?
Validate semantics after validating shape. Require the expected number of rows, numeric bounds, units, rank or date ordering, and a citation to the exact source element. For a price, compare the currency and product identifier; for a ranking, compare the visible rank; for a count, reject formatted text that cannot be parsed unambiguously. If any invariant fails, return an error with evidence instead of a plausible-looking number.
Our Stagehand run demonstrates why this matters: the response satisfied the requested TypeScript shape while selecting ranks 22 to 24. A second deterministic read of the source page caught the error. The same pattern applies to local Ollama models, where a smaller model may be useful for classification but unsuitable for multi-step navigation or exact extraction without a validator.
Can a local AI model run this reliably?
Sometimes, but hardware and task shape matter more than the word local. A MacBook can run a local model for short classification or a constrained extraction, yet long context, screenshots, tool schemas, and multi-step recovery quickly increase memory and latency. Test the exact model, quantization, context size, browser, and timeout on the target machine. Do not infer production reliability from a single successful chat response.
A practical pattern is to let deterministic code handle navigation and use the local model only for a bounded decision. Log wall time, tokens, memory pressure, retries, and the percentage of outputs that pass source checks. If a local model cannot meet those thresholds, switch only that step to a hosted provider or a larger model rather than rebuilding the whole browser workflow.
How can a non-expert automate one annoying task?
Start with a read-only task that has a clear finish line: collect a short list, copy a report, or summarize one page into a file. Write the starting URL, allowed domains, expected output, and stop conditions in plain language. Run it in a separate browser profile or ego (lite) Space, inspect the first result, and only then add pagination or a second site.
For example, an email-to-RAG workflow should first extract each question into a numbered JSON array, preserve the email subject and timestamp, and ask for review before indexing. That small contract is easier to debug than asking an agent to read an entire inbox and decide what matters. Once the read-only path is repeatable, add human-approved writes one action at a time.
What does each one require to run?
The visible API is only part of setup. The real first-run surface includes language runtimes, browser binaries or services, model access, profiles, and the place where results are validated.
| Product | Minimum practical setup | Price boundary checked on August 25, 2026 |
|---|---|---|
| Browser Use | Python 3.11+, package or CLI, a supported provider or configured local model, browser/profile choice, and result validation | MIT package is free to self-host; model and browser infrastructure cost extra; optional Browser Use Cloud is usage-priced |
| Stagehand | Current language SDK, ESM-compatible setup for TypeScript, local or Browserbase browser, and a supported model or client callback for AI primitives | MIT SDK is free to self-host; model and browser costs remain; Browserbase is an optional managed production path |
| ego (lite) | Desktop app, one-time ego-browser skill setup, and a shell-capable coding agent that can write and verify the workflow | macOS download was free; Windows remained a waitlist; the coding agent's own plan or API usage is separate |
The first-run diary exposed different kinds of friction. Browser Use installed many Python dependencies and browser extensions. Stagehand v4 required Node 22.18+, ESM, careful local path handling, and a client callback for our local model. ego (lite) was already installed, but its skill text and screenshot helper were out of sync. None of those facts alone decides production fit; they tell you what your team will have to own.
How should you think about sessions?
Browser Use documents real-browser profile reuse and profile sync. Stagehand local-browser options expose userDataDir and profile preservation, while Browserbase provides managed session paths. ego (lite) starts from a persistent desktop browser and keeps agent work inside separate Spaces.
Choose Browser Use or Stagehand when your application should provision and own the browser profile or remote session. Choose ego (lite) when an existing coding agent should work from a persistent, visible desktop browser where it inherits your real Chrome logins. Whichever route you take, define which accounts, domains, and actions the agent may reach before connecting valuable accounts.
For the connection models themselves, read our guide to how agents connect to an existing browser and the browser-agent security checklist before using valuable accounts.
Which one should you choose?
Choose Browser Use when discovery is the job
If the agent must discover an unfamiliar route, adapt across changing pages, and decide what action comes next, Browser Use gives you the right top-level abstraction. Budget for a capable model, traces, timeouts, retries, and an independent validator. The direct browser APIs are still available when a deterministic escape hatch is needed.
Choose Stagehand when the workflow belongs in code
If an engineering team owns the browser workflow, the stable route should remain code and tests. Call extract or act only for the variable part, then check the output against source-page invariants. Stagehand is especially compelling when Browserbase already fits the deployment model, but local browser execution is available too.
Choose ego (lite) when a coding agent needs its own persistent browser
If Codex, Claude Code, or another shell-capable agent is already doing the planning and writing code, adding a second browser-agent framework can be redundant. ego (lite) supplies what is missing, a free full Chromium that your coding agent drives against real sites.
Choose Playwright when the task is fully deterministic
If the DOM and route are known, neither a full agent loop nor an AI extract may be necessary. A lower-level automation library is easier to test and cheaper to reason about. Our Browser Use vs Playwright comparison covers that boundary directly.
What are the real limitations?
Browser Use
The framework gives you autonomy, not guaranteed correctness. Model context, latency, provider behavior, browser profiles, and validation become operator concerns. Our local 4B model could not complete step one within 180 seconds, which makes local-model suitability a real setup question even though the browser layer itself worked.
Stagehand
Stagehand is a developer SDK. You still design the workflow, operate the browser, configure the model path, and build result checks. Schema validity is not semantic validity; our wrong-row extract is the exact failure a production invariant should catch.
ego (lite)
ego (lite) is strongest when a shell-capable coding agent needs persistent browser state, an isolated task Space, and a human-visible takeover path on macOS. It keeps planning in the coding agent and browser execution in a dedicated desktop environment. For unattended CI, standalone autonomous navigation, or server-side browser fleets, compare the headless and real-browser trade and choose infrastructure designed for that operating model. The helper mismatch we observed is also a practical reason to keep the installed skill and app versions aligned.
FAQ
Is Stagehand built on Playwright?
No. Current Stagehand v3 and later are CDP-native. The SDK keeps familiar Playwright-style methods so browser developers do not have to relearn basic navigation and locator concepts, but Playwright is not its current runtime foundation.
Can I use Stagehand without Browserbase?
Yes. Stagehand v4 exposes a localBrowser path as well as Browserbase launch and connect paths. We used localBrowser for this test. Browserbase becomes relevant when managed sessions, proxies, observability, or production browser infrastructure match your deployment needs.
Stagehand vs Browser Use: which is better for scraping?
For known sites and exact fields, Stagehand's deterministic-first shape is usually easier to validate. For unknown sites where the route itself must be discovered, Browser Use's autonomous loop is the stronger starting point. If the sources sit in a persistent personal browser and a coding agent already owns the task, ego (lite) is a third architecture rather than a drop-in SDK substitute.
Can all three keep login state?
All three expose a session strategy, but through different ownership models. Browser Use can reuse or sync profiles. Stagehand can preserve a local user data directory or use managed Browserbase sessions. ego (lite) is built around persistent browser state and isolated Spaces. None of that proves automatic compatibility with every site or account.
Does the Browser Use timeout mean Stagehand is faster?
No. We tested a native Browser Use Ollama adapter and a custom Stagehand client callback, with different prompts and control loops. The timeout shows that our local qwen3:4b Browser Use configuration was not usable for this task. It does not rank Browser Use with recommended hosted models against Stagehand.
Which option is cheapest?
There is no honest universal answer. Browser Use and Stagehand are free to self-host, then inherit model, browser, proxy, and operator costs; their managed services are separate. ego (lite) was free for macOS on the research date, but the coding agent still has its own plan or API cost. The cheapest correct architecture is the one that avoids unnecessary model calls without removing needed autonomy.
Do any of them bypass CAPTCHAs reliably?
Do not choose any of the three from a universal bypass claim. Browser Use Cloud and browser-infrastructure vendors offer CAPTCHA-related services, while persistent profiles can reduce some repeated challenges, but site behavior changes and anti-bot systems are adversarial. We did not test CAPTCHA handling in this experiment.